Why One Kubernetes Node Hit 96% Utilization While Another Sat at 48%
Diagnose uneven node utilization by reviewing pod placement, resource requests, topology spread constraints and autoscaling behavior.
4 min read
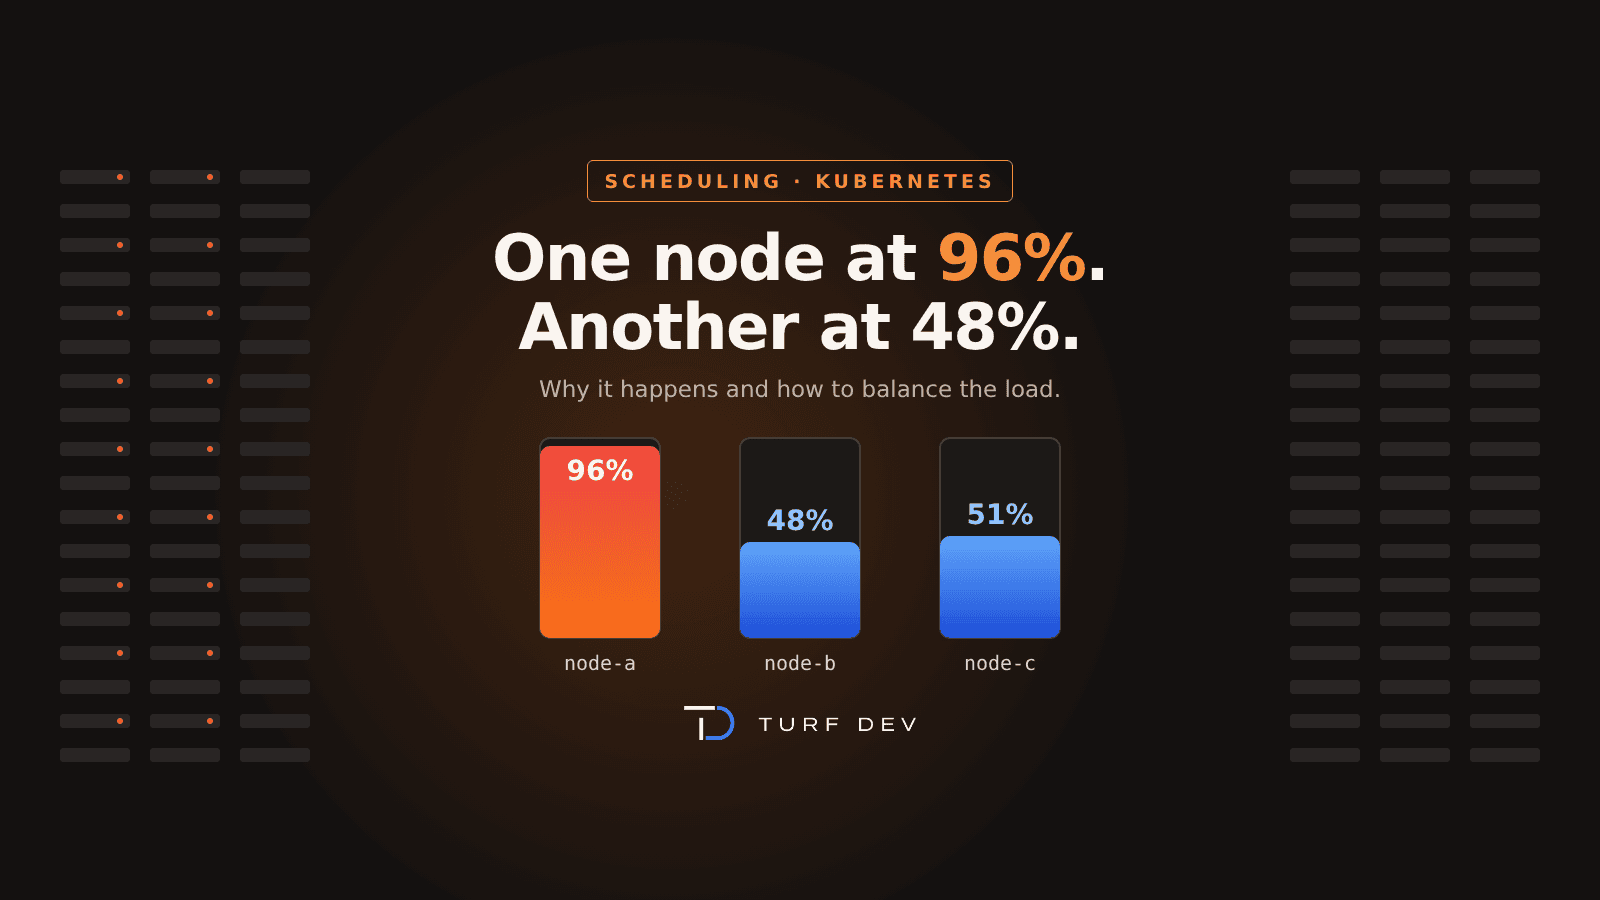
A cluster was set to autoscale between 2 and 10 nodes. On paper, it had room. In practice, one worker sat at 96% CPU, another at 78%, and a third at 48%.
The instinct is to add nodes. But more nodes don't help if the scheduler keeps stacking the busiest pods on the same machine. Before adding infrastructure, we asked one question: why was one worker at 96% while another sat at 48%?
1. Start with pod placement
Node metrics show how busy each worker is, not which workloads cause it. First, see where the pods actually landed:
kubectl get pods -n <namespace> -o wideThen compare with node usage:
kubectl top nodesA common assumption is that three replicas on a three-node cluster land one per node. Kubernetes does not guarantee that. Without spread rules, two or even three replicas can end up on the same node.
2. Requests vs actual usage
The scheduler places pods using their resource requests, not their real usage. If a pod requests 100m CPU but uses 900m, the scheduler thinks the node has plenty of room and keeps adding pods to it.
See what each node has been promised:
kubectl describe node <node-name>Look at the "Allocated resources" section near the bottom. Then compare with real usage per pod:
kubectl top pods -n <namespace>3. What usually causes it
When one node runs hot and others sit idle, we usually find a combination of three things:
Replicas stacked on one node. Nothing tells the scheduler to spread them.
Requests set too low. The busiest pods look small to the scheduler, so it packs them together.
The autoscaler never triggers. It scales on pending pods and requests, not CPU usage, so it sees no reason to add a node.
4. Improve the scheduling strategy
The fix is to tell the scheduler how to spread replicas. Add a topologySpreadConstraint to the Deployment's pod spec with these settings:
topologyKey: kubernetes.io/hostname spreads replicas across nodes.
maxSkew: 1 keeps the difference between nodes to at most one replica.
whenUnsatisfiable: ScheduleAnyway prefers spreading but never blocks a pod.
labelSelector matches your app's labels, for example app=backend.
These settings go under spec.template.spec.topologySpreadConstraints in your Deployment.
5. What does maxSkew: 1 do?
maxSkew is the largest allowed difference in replica count between any two nodes. With maxSkew: 1 and three replicas on three nodes, the scheduler aims for 1-1-1. It will not place a second replica on a node while another node has none.
6. Why ScheduleAnyway?
The other option, DoNotSchedule, is a hard rule. If the spread can't be met, for example during a node drain, new pods stay Pending.
ScheduleAnyway makes the spread a strong preference. Pods still start during disruptions, and the scheduler rebalances as capacity returns. For most web workloads, that is the safer default.
7. Scheduling rules aren't enough
Spread rules decide where new pods go. They don't fix everything:
Right-size requests. Set CPU and memory requests close to real usage, so the scheduler and autoscaler work from honest numbers.
Existing pods don't move. Spread rules apply only when pods are scheduled. Restart the Deployment to re-place them.
Protect availability. Add a PodDisruptionBudget so rebalancing never takes all replicas down at once.
To re-place existing pods after the change:
kubectl rollout restart deployment/<deployment-name> -n <namespace>8. Validate the change
Check that replicas are now spread across nodes:
kubectl get pods -n <namespace> -o wideThen watch node usage under real traffic for a day:
kubectl top nodesLook for nodes within a reasonable band of each other, and for the autoscaler adding nodes when pods go Pending.
9. Balanced doesn't mean equal
You will never see 60-60-60. Different pods do different work, and system components add their own load. The goal is no hotspots: no single node close to its limit while others sit idle.
The engineering takeaway
When nodes are uneven, don't start by adding nodes. Check placement, compare requests with real usage, add spread rules, right-size requests, and then let the autoscaler do its job with accurate numbers.
How Turf Dev can help
Turf Dev reviews Kubernetes clusters for scheduling, resource requests and autoscaling setup, so capacity goes where it is needed and the cloud bill matches real usage. If your nodes look uneven or your autoscaler never seems to help, reach out at turfdev.in.
1 of 2 sections shown
Discussion
Have a question or something to add? Share it below.
No comments yet. Be the first to join the discussion.